MediumProblem 18 of 36 in the system design series
Design a News Aggregator: Crawling, Dedup and Personalised Feeds
A news aggregator collects articles from thousands of publishers, folds coverage of the same event into a single story, and presents each reader with a ranked feed tuned to their interests. Tapping a headline sends the reader to the original publisher's page. Think of a Google News-like product, designed here as interview practice rather than as an account of how any particular company built theirs.
The question rewards candidates who notice its lopsided shape. Content arrives as a modest trickle, while reads arrive as a flood every morning. A good answer treats ingestion and serving as separate pipelines, one optimised for correctness and deduplication and the other for low latency at enormous read volume.
The challenging parts sit at both ends. On the way in, the same report shows up under many URLs and in lightly edited syndicated copies, and the system must recognise them. On the way out, every user expects a fresh, personal feed in a fraction of a second, which is impossible if each request ranks the whole catalogue from scratch.
This is an interview practice design for a News Aggregator-like service, built from first principles. It is not a description of how News Aggregator is actually built.
Functional Requirements
Ingestion comes first: the system pulls new articles from a large set of publishers through their RSS feeds and sitemaps. Next comes grouping. When dozens of outlets cover the same election result, a reader wants one story card listing all of them, not ten nearly identical headlines in a row.
Each reader then gets a personalised feed ordered by their interests, their location and how recent the news is. Finally, opening a story links out to the publisher's own site, which keeps publishers willing to be included and spares us from hosting full articles. Paywall handling, comment threads and full-text search would all be useful additions, but they sit on top of this core and are left for later.
Ingest articles
Pull new articles from thousands of publisher feeds and sites.
RSS · sitemaps
Group duplicates
The same story from many sites shows up once, as one cluster.
story clusters
Personalised feed
Each user sees fresh stories ranked by their interests.
topics · location
Read at the source
Tapping a story opens the publisher's own page.
link out
- Out of scope today: paywalls, comments and full-text search
Non-Functional Requirements
Freshness is what readers come for. A major development ought to reach readers in roughly five minutes, a target that sets an upper bound on how slowly we can crawl and process. Speed matters at the other end: a feed request should complete with p99 latency under 200 milliseconds even during the morning rush, when many people open the app at once.
The workload is overwhelmingly read-heavy. Millions of readers request feeds, while new articles trickle in comparatively slowly. That asymmetry justifies heavy caching and precomputation. Availability beats strict consistency as well: a feed that is a minute behind is perfectly acceptable, but a blank screen because ranking timed out is not. Designing for graceful staleness makes every caching decision easier.
Fresh
Breaking news shows up within a few minutes.
< 5 min to feed
Fast feed
The feed loads almost instantly.
p99 < 200 ms
Read-heavy scale
Millions of readers, far fewer new articles.
reads ≫ writes
Available
A slightly stale feed is fine; an empty feed is not.
eventual consistency
Scale Estimation
Assume we follow about 100,000 publisher feeds and check each roughly every five minutes, which works out to around 330 fetches per second. Assume those feeds yield about 2 million new articles per day, or only about 23 per second. Ingestion is genuinely small.
Reads tell a different story. Assume 100 million daily active users, with a typical reader checking in around 10 times daily, giving roughly 1 billion feed loads daily, about 12,000 per second on average and perhaps 50,000 per second at the morning peak. The write-to-read ratio is so skewed that the design should do expensive work once and reuse it: precompute and cache as much of each feed as possible rather than ranking on demand.
100K
Feeds crawled
every ~5 min ≈ 330 fetches/s
2million
New articles per day
≈ 23 / s — tiny
100million
Daily active users
≈ 10 feed loads each
12K avg
Feed loads per second
≈ 50K at morning peak
Writes are tiny, reads are huge → precompute and cache feeds
Core Entities & API
Three entities matter. An article is a single piece from one publisher. A story groups the articles covering one event, and it is the unit readers actually see in their feed. A user profile captures interests, followed topics and location, and drives personalisation.
Reading uses GET /feed?cursor=&limit=20, returning a page of ranked stories and a cursor for the next page, which keeps infinite scroll stable. GET /stories/{id} returns a story's headline and all its articles, letting the reader choose which outlet to open. Behavioural signals such as clicks and hides go to POST /events, which replies 202 because the events are processed asynchronously. Accepting them quickly keeps the app responsive while still feeding the personalisation pipeline.
Core entities
ArticleStory (cluster)User profile
API
- GET /feed?cursor=&limit=20→ { stories[], next_cursor }
- GET /stories/{id}→ { headline, articles[] }
- POST /events { story_id, type: click | hide }→ 202 accepted
High-Level Design
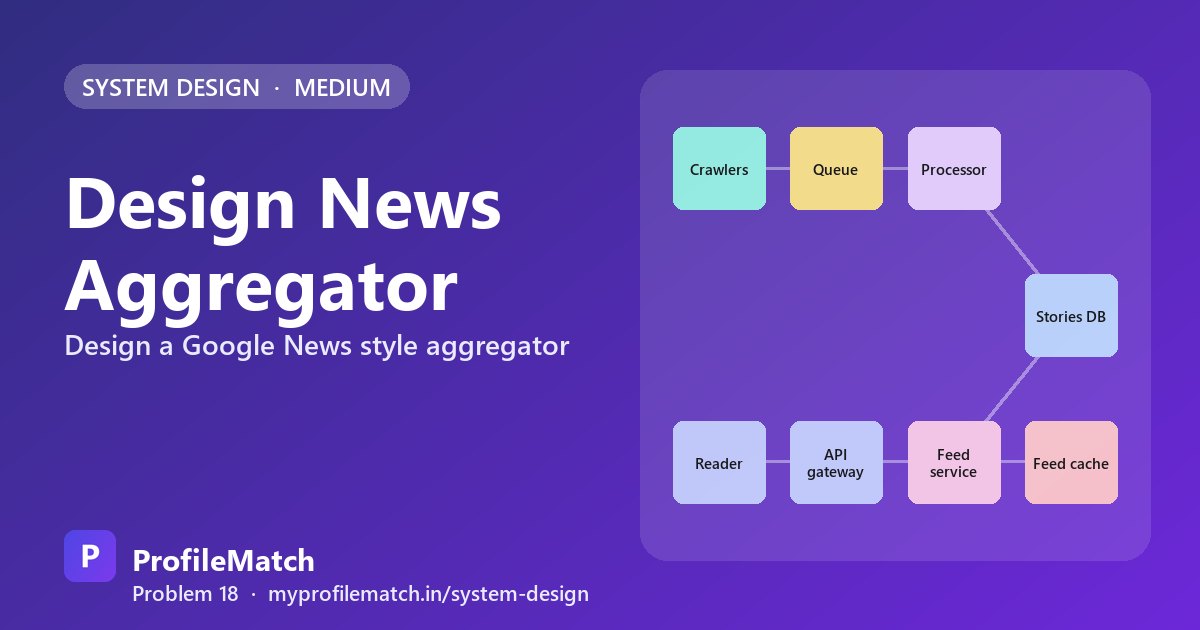
The architecture splits into an ingestion half and a serving half. On the ingestion side, crawlers fetch publisher feeds and sitemaps on a schedule and push each new article onto a Kafka topic. The queue decouples crawling speed from processing speed and lets processing replay articles if a bug is fixed later.
A processor consumes the topic, extracts the headline, body text and lead image, drops duplicates, attaches the article to a story cluster and tags topics. Results are written to a stories database holding both articles and clusters.
On the serving side, a reader's request passes through an API gateway to a feed service. The feed service checks a Redis feed cache first, and the large majority of loads end there. On a miss, it pulls candidate stories from the database, ranks them for that user and caches the outcome for a few minutes, so the next several opens are cheap.
Deep Dive 1 — Ingestion & Dedup
Polling every feed at the same rate is wasteful, so polling adapts to each source: busy newsrooms are checked every minute and sleepy blogs hourly. Conditional requests with ETag headers mean an unchanged feed returns a tiny 304 response, saving bandwidth for both sides.
Exact duplicates are handled cheaply. The same article frequently surfaces under several URLs with tracking parameters attached, so the processor normalises each URL, strips those parameters, hashes the result and drops anything it has seen before. Near duplicates need more care, because syndicated wire stories are republished with small edits. For those, the processor computes a 64-bit SimHash, a fingerprint where similar text yields fingerprints differing in few bits. Two fingerprints within 3 bits of each other are treated as the same article. Splitting fingerprints into bands lets the system look up only a handful of candidates rather than comparing against everything.
Different articles about one event are not copies, so a final step clusters them into stories. It compares text embeddings, looks for shared named entities such as people and places, and only groups pieces published within a sensible time window of each other.
- 1Adaptive pollingBusy feeds every minute, quiet ones hourly; use ETags
- 2Exact duplicatesNormalise the URL, hash it, skip if already seen
- 3SimHash fingerprint64-bit fingerprint; similar text → similar bits
- 4Near-duplicate check≤ 3 bits differ → same article, found via bit bands
- 5Cluster into storiesEmbeddings + entities + time window → one story
Deep Dive 2 — Ranking & Personalisation
Ranking begins by narrowing the field. Candidates come from the topics a user follows, their city and what is trending, typically a few hundred recent stories. Scoring the entire database per request would be pointless and slow.
Each candidate then receives a score combining several signals: a freshness decay over hours, the quality of the sources involved, the size of the story measured by how many publishers covered it, and the user's affinity for its topics. A story about a national budget covered by fifty outlets and matching a reader's interest in economics should outrank a minor local item from yesterday.
The system learns from behaviour. Clicks, read time and hides stream into a compact per-user topic profile that adjusts affinities over time. Diversity rules then shape the final list: avoid five stories on one sport in a row, mix sources, and always slot in a few top stories everyone should see, which keeps readers from drifting into a narrow bubble.
Generate candidates
Fresh stories from followed topics, your city, and what's trending — a few hundred.
Score each story
Freshness decay × source quality × story size × user interest.
Learn from behaviour
Clicks, read time and hides update a per-user topic profile.
Keep it diverse
Mix topics and sources; always include a few top stories for everyone.
Deep Dive 3 — Caching Feeds
Ranking every request from scratch guarantees freshness, but at around 50,000 loads per second the compute bill is enormous and latency suffers at peak. Precomputing a full feed for every user makes reads instant, yet burns work on people who will not open the app today and leaves feeds stale the moment big news lands.
The chosen design splits shared and personal work. Every minute, a job rebuilds the top story lists for each topic and region, and millions of users read those same lists. A personal feed is then just a merge and re-rank of a few relevant lists, cheap enough to compute lazily and cache for a few minutes. When a major story breaks, the affected topic lists are rebuilt immediately and short TTLs on personal feeds ensure the update reaches readers quickly. The logged-out front page is identical for everyone and is served straight from a CDN.
Rank on every request
- + Always fresh
- − Heavy compute at 50K/s
- − Slow under peak
Precompute every user
- + Instant reads
- − Wasted on inactive users
- − Stale on breaking news
Shared + user cachesChosen
- + Shared work done once
- + Fresh within minutes
- − Two cache layers
- Top stories per topic & region rebuilt every minute → shared by millions
- Big story breaks → refresh topic lists, short TTL on user feeds
- Logged-out front page served from a CDN
Trade-offs
Crawling more often improves freshness but raises our costs and the load we place on publisher servers, which is why adaptive polling matters. The SimHash threshold is a balancing act: set it too strict and syndicated copies leak through as separate items, set it too loose and genuinely different reports get merged.
Precomputed feeds are fast but wasteful, and on-demand ranking is fresh but costly; the shared-plus-personal cache sits between them. Personalisation raises relevance but risks a filter bubble, so diversity rules and shared top stories stay in place. The overall approach is to crawl selectively, remove duplicates as early as possible, do common work once, and leave the personal touch until the final step.
Freshness vs crawl cost
Polling more often is fresher, but costs us and the publishers more.
Strict vs loose SimHash threshold
Too strict lets copies slip through; too loose merges different stories.
Precompute vs on-demand ranking
Precompute is fast but wasteful; on-demand is fresh but expensive.
Personalisation vs filter bubble
More relevance, but keep diversity rules and shared top stories.
Crawl smart. Dedupe early. Share the work, personalise late.
Key takeaways
- Writes are tiny (about 23 articles per second) while reads peak near 50K per second, so precompute and cache feeds.
- Adaptive polling with ETags keeps crawling cheap while meeting a roughly five-minute freshness target.
- Catch exact duplicates by URL hash and near duplicates by SimHash, then cluster articles into stories.
- Rank a few hundred candidates using freshness, source quality, story size and user interest.
- Rebuild shared topic lists every minute and merge them into short-lived personal feeds.
Interview questions
How does a news aggregator detect duplicate articles from different sites?
It uses two layers. Exact duplicates are caught by normalising URLs, removing tracking parameters and hashing them. Near duplicates, such as lightly edited syndicated copies, are caught with SimHash: each article gets a 64-bit fingerprint, and fingerprints that differ in only a few bits are treated as the same article. Banding the fingerprints keeps the comparison to a small candidate set.
How are related news articles grouped into a single story?
Articles that report the same event but are not copies are clustered using text embeddings, shared named entities such as people, organisations and places, and a publication time window. If a new article is close enough to an existing cluster on these signals, it joins that story; otherwise it starts a new one. Readers then see one story card listing every outlet covering it.
How does a news feed stay fresh if it is cached?
Shared topic and region lists are rebuilt every minute, and personal feeds built from them are cached with short TTLs of a few minutes. When a major story breaks, the relevant topic lists are refreshed immediately. Because personal feeds merge these lists, the breaking story appears as soon as each user's short-lived cache entry expires, without recomputing everything.
How do you personalise a news feed without ranking every article?
Start by generating a few hundred candidates from the user's followed topics, their location and trending stories, mostly drawn from shared precomputed lists. Score only those candidates using freshness, source quality, story size and the user's topic affinity, then apply diversity rules. The per-user topic profile is updated from clicks, read time and hides as a stream.
How often should a news aggregator crawl publisher feeds?
It should adapt to each source. Feeds that publish frequently are polled about every minute, while quiet sources are checked hourly. Conditional requests with ETags make unchanged feeds almost free to check. Polling more often improves freshness but costs bandwidth for both the aggregator and the publisher, so the schedule balances the five-minute freshness goal against crawl cost.
Keep practising
- Learn the building blocks in the free system design course.
- Rehearse answers with system design interview questions.
- See which open jobs fit your skills: upload your resume.