HardProblem 27 of 36 in the system design series
Design Facebook Post Search: Keyword Search Over Trillions of Posts
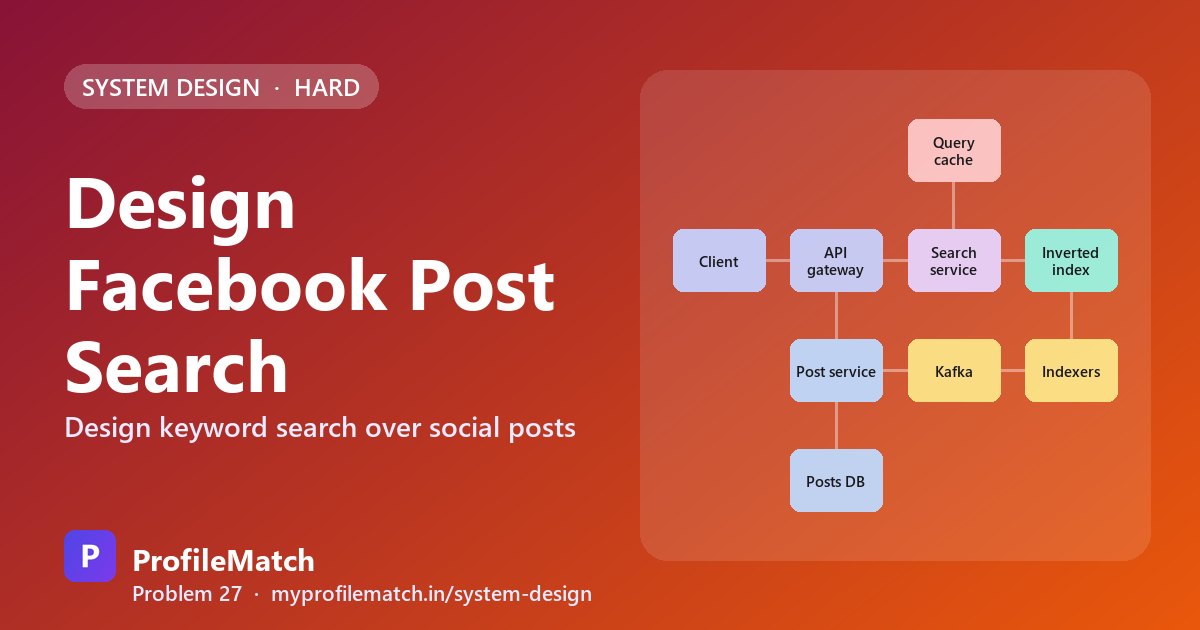
Post search on a large social network lets someone type a few words and get back every public post containing them, ordered either by recency or by popularity. This practice design targets a Facebook-like service where billions of people publish and react to content every day.
Interviewers use this problem because it forces a candidate to build search from first principles instead of reaching for a database query. You have to explain what an inverted index is, how it is partitioned across hundreds of machines, and how a query fans out and comes back together within a strict latency budget.
The twist is the write load. Reactions arrive far more often than searches, and each one can change a post's position in like-sorted results. A design that rebuilds index entries on every like will drown, so much of the work goes into making updates cheap while keeping results fresh enough that users never notice the lag.
This is an interview practice design for a Facebook Post Search-like service, built from first principles. It is not a description of how Facebook Post Search is actually built.
Functional Requirements
Two write actions feed the system: publishing a post and liking one. On the read side, a user enters one or more keywords and receives only posts that contain every term, which is AND semantics rather than any-match. Results can be ordered newest first or most liked first, and a cursor lets the client keep scrolling.
Privacy rules, per-user ranking and spelling correction are excluded on purpose. Each would add a separate subsystem, such as an access-control filter or a learned ranker, and none changes the fundamental index structure. Keeping them out lets the discussion stay on indexing, partitioning and freshness.
Create & like posts
Users publish posts and like them.
post · like
Search by keyword
Find posts that contain all the words in the query.
multi-word
Sort results
By most recent, or by most liked.
recency · likes
Paginate
Scroll through more results with a cursor.
next page
- Out of scope: privacy filters, personalised ranking, typo tolerance
Non-Functional Requirements
Latency target is under 500 ms per query, and that has to hold for extremely common words, which are exactly the terms with the longest index entries. Freshness is the second pillar: a newly published post should appear in results within about a minute, because people search for things that are happening right now.
The system must absorb billions of writes daily and remain available through machine failures. Since a like total that is a few seconds old harms nobody, we explicitly favour availability over strict consistency. That single decision unlocks batching and caching techniques that would be off the table if counts had to be exact at every instant.
Fast search
Results come back quickly, even for common words.
< 500 ms
Fresh results
A new post becomes searchable almost immediately.
< 1 minute
Massive scale
Billions of new posts and likes every day.
write-heavy
High availability
Search stays up; slightly stale counts are fine.
eventual consistency
Scale Estimation
Assume one billion new posts per day, which is about 12,000 writes per second. Likes are ten times as frequent, around ten billion a day or roughly 115,000 per second. Searches come to about 500 million per day, near 6,000 per second. Retained for ten years, posts accumulate to roughly 3.6 trillion documents in the index.
Two conclusions fall out. First, an index covering trillions of documents must be spread across many machines, so partitioning is mandatory. Second, likes outnumber searches by about twenty to one, so the dominant cost is not answering queries but keeping the index current. Every design choice that follows tries to make updates cheap.
1billion
New posts per day
≈ 12K writes / s
10billion
Likes per day
≈ 115K / s
500million
Searches per day
≈ 6K / s
3.6trillion
Posts to index
10 years × 1B / day
Likes outnumber searches 20 : 1 → make index updates cheap
Core Entities & API
User, Post and Like are the only entities needed. A post stores its author, text and creation time; a like links a user to a post. The like count per post is derived and lives both in the source database and, approximately, in the index.
POST /posts accepts content and returns a post_id. POST /posts/{post_id}/like records a reaction. Search uses GET /search with a query string, a sort mode of recency or likes, and an opaque cursor; it returns a page of posts plus next_cursor. Cursor pagination is preferable to page numbers because new posts keep arriving, and offsets would shift results between requests.
Core entities
UserPostLike
API
- POST /posts { content }→ { post_id }
- POST /posts/{post_id}/like→ 200 OK
- GET /search ?q=cricket final&sort=likes&cursor=→ { posts: [...], next_cursor }
High-Level Design
Traffic enters through an API gateway that sends reads and writes down separate paths. On the read path, the search service first checks a Redis cache for that exact query. On a miss, it fans the query out to every index shard, gathers their partial results and merges them into one ordered page.
On the write path, the post service persists posts and likes in the primary database, which is the source of truth, and emits an event to Kafka for each change. Indexer workers consume those events, tokenise post text, and apply additions and like-count updates to the in-memory inverted index.
Treating the index as derived data is a deliberate safety valve. If a shard is corrupted or lost, it can be reconstructed by replaying Kafka or by rescanning the posts database, so the index never needs the same durability guarantees as the primary store.
The index is derived data → we can always rebuild it from Kafka
Deep Dive 1 — Inverted Index
Indexing a post starts with normalisation: lowercase the text, break it into words and strip punctuation, so "Cricket!" and "cricket" map to the same term. For each term the index stores a posting list, the set of post IDs that contain it, much like the index pages at the end of a textbook.
Each posting list is maintained twice, once ordered by creation time and once by like count, so either sort mode can read entries in final order without sorting at query time. For a two-word query, the search reads both lists and intersects them; only IDs present in both survive. For example, if one word maps to posts 9, 7 and 3 and the other to 9, 4 and 3, the answer is 9 and 3.
Because the lists are pre-sorted, the intersection can walk from the top and stop the moment one page of matches is assembled. Even a term that appears in billions of posts costs only a short scan, which is how common-word queries stay inside the latency budget.
- 1TokeniseLowercase, split into words, drop punctuation
- 2Posting listsword → list of post IDs that contain it
- 3Two sort ordersOne list by time, one by like count
- 4IntersectMulti-word query: posts present in every list
- 5Stop earlyLists are sorted, so take the top page and stop
- "cricket" → [p9, p7, p3] · "final" → [p9, p4, p3] → [p9, p3]
Deep Dive 2 — Sharding & Ranking
Partitioning by term places each word's entire posting list on one shard, so a query touches only a handful of machines. The catch is skew: everyday words produce gigantic lists and attract most of the traffic, creating hot shards that are hard to rebalance.
Partitioning by post ID is the chosen approach. Each shard holds a complete mini-index over its own subset of posts, load spreads evenly, and a new post or like touches exactly one shard. The price is that every query must visit every shard. In this scatter-gather pattern every shard reports its 25 best local candidates, and the coordinator combines those lists into the final 25.
Tiering keeps the hardware bill reasonable. Recent posts, which satisfy most searches, live in memory; older posts sit on SSD and are consulted only when the recent tier cannot fill a page. Because like ordering inside the index may lag slightly, the final candidates are re-ranked using current like totals just before the response is returned.
Shard by word
- + A query hits few shards
- − Hot words = hot shards
- − Huge lists for common words
Shard by post IDChosen
- + Even load, easy to grow
- + A write touches one shard
- − Every query hits all shards
- Scatter-gather: each shard returns its top 25; merge into a global top 25
- Tiers: recent posts in RAM; older posts on SSD, searched only if needed
- Re-rank the final top results with fresh like counts
Deep Dive 3 — Freshness & Caching
Kafka between the write services and the indexers smooths bursts. When a major event triggers a flood of posts, the backlog grows in the log rather than overloading index shards, and indexers drain it at a steady pace. Like updates get extra treatment: a post going viral may receive thousands of likes per second, so indexers accumulate per-post deltas for a few seconds and apply one combined update.
New documents become visible through a near-real-time refresh that runs roughly once a second, so freshly published posts are searchable almost immediately. Popular queries are cached in Redis for 30 to 60 seconds, which means a trending topic searched by millions hits the shards only once per expiry. Each shard also runs several replicas, spreading read traffic and keeping search available when individual machines fail.
Kafka decouples writes from indexing
Spikes of posts and likes wait in the queue instead of crushing the index.
Batch like counts
Sum likes per post for a few seconds; one index update instead of thousands.
Near-real-time refresh
New posts become visible to search every second or so.
Cache hot queries with a short TTL
Top results cached 30–60 s; trending queries rarely touch the shards.
Replicas for every shard
Spread read load, and keep serving when a machine dies.
Trade-offs
Choosing post-based sharding gives balanced load and single-shard writes, but every query pays a fan-out to all shards, which raises tail latency and makes replica health important. Batching likes slashes index write volume, yet like-sorted results can trail reality by a few seconds.
Caching hot queries yields large savings during spikes, with the downside that a cached page may be up to a minute old. Finally, a managed engine such as Elasticsearch would be the fastest way to ship, while a purpose-built index offers tighter control over memory layout, tiering and update batching once the corpus reaches trillions of documents.
Shard by post vs by word
Even load and simple writes — but every query fans out to all shards.
Batching likes
Far fewer index writes — but like-sorted results lag a few seconds.
Caching hot queries
Huge savings — but cached results can be up to a minute old.
Elasticsearch vs a custom index
Fast to build — but at Facebook scale, a custom system gives more control.
Shard by post. Batch the writes. Cache the hot queries.
Key takeaways
- Build an inverted index: each word maps to a posting list of post IDs, kept sorted by time and by likes.
- Intersect posting lists for multi-word queries and stop once one page is full.
- Shard by post ID for even load; scatter the query to all shards and merge their local top results.
- Likes outnumber searches about 20 to 1, so batch like updates and route writes through Kafka.
- Cache trending queries briefly, keep recent posts in RAM and re-rank final results with fresh counts.
Interview questions
Why not use SQL LIKE queries for post search?
A pattern such as LIKE '%word%' cannot use an ordinary B-tree index, so the database scans every row and checks the text. With trillions of posts that takes far too long. An inverted index flips the problem: it maps each word to the posts that contain it, so a query jumps directly to the matching IDs instead of examining every document.
How does an inverted index handle multi-word search queries?
Each word in the query has its own posting list of post IDs. The search engine reads those lists and intersects them, keeping only IDs that appear in all of them, which gives AND semantics. When the lists are stored in the same sort order, the intersection is a fast merge walk, and it can stop as soon as one page of results is collected.
How do you search for a very common word quickly?
Keep posting lists pre-sorted in the order results will be shown, by time or by likes. The engine then reads from the head of the list and stops once it has enough matches for one page, instead of scanning millions of entries. Caching popular queries for under a minute and keeping recent posts in memory make common terms even cheaper.
How quickly does a new post become searchable?
Typically within a few seconds. The post service saves the post and emits an event to Kafka, an indexer consumes it and adds the post's terms to the in-memory index on its shard, and a near-real-time refresh about once per second makes the change visible to queries. Cached results for popular searches may take up to their TTL to reflect it.
Should a search index be sharded by term or by document?
Sharding by term means a query visits few shards, but popular words create oversized, overloaded partitions. Sharding by document spreads data and writes evenly and keeps each update on one shard, at the cost of querying every shard and merging results. For a write-heavy social network, document sharding with scatter-gather usually wins because load stays balanced.
Keep practising
- Learn the building blocks in the free system design course.
- Rehearse answers with system design interview questions.
- See which open jobs fit your skills: upload your resume.