HardProblem 21 of 36 in the system design series
Design YouTube Top K: Most Viewed Videos Over Sliding Windows
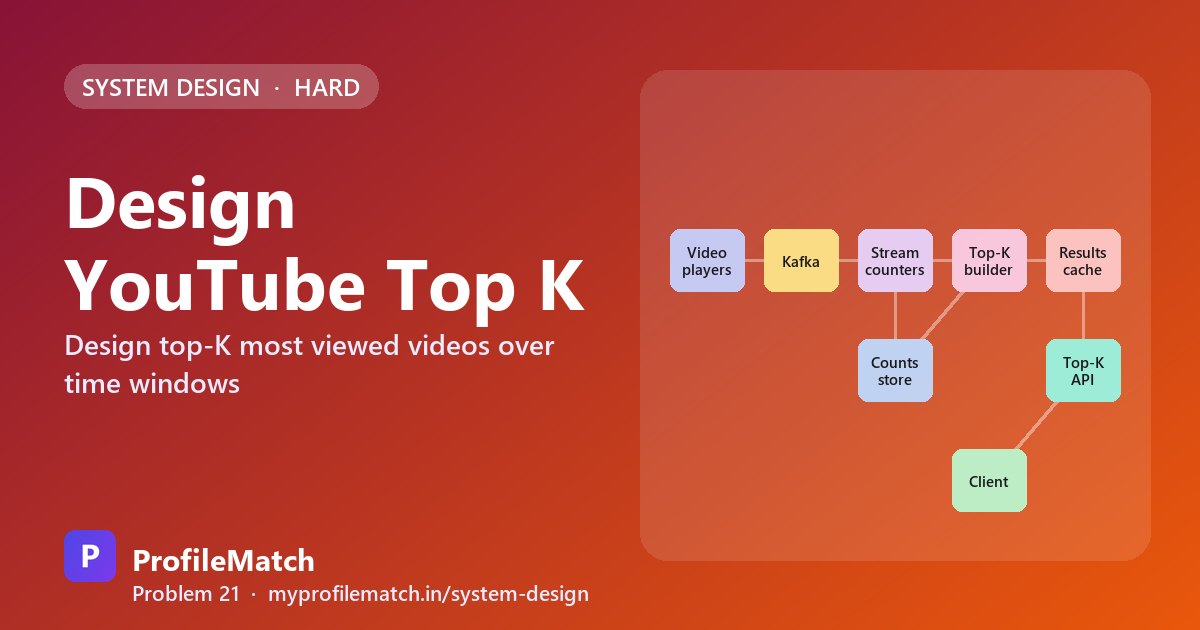
A top-K service answers a simple-sounding question: which K videos were watched most in the past hour, day, month, or ever? On a video platform with billions of daily views, that question powers trending pages, editorial dashboards and recommendation signals, and it has to be answered in milliseconds while the underlying numbers change constantly.
Interviewers pick this problem because the obvious solution, a table of counters sorted on demand, collapses immediately under the write rate. It forces a candidate to reason about stream processing, partitioning, memory budgets and windowed aggregation, and to take a position on whether an approximate answer is good enough.
The difficulty is the mismatch between input and output. Hundreds of thousands of events arrive every second, yet each answer is a list of at most a thousand IDs. Bridging that gap cheaply, and keeping the list correct as windows slide forward, is the core of the design.
This is an interview practice design for a YouTube Top K-like service, built from first principles. It is not a description of how YouTube Top K is actually built.
Functional Requirements
There are three requirements. Every view must contribute to the rankings; we cannot sample or drop events. A client can request the top K videos, where K is capped at 1,000, and receive each video's view count alongside its ID. Finally, rankings exist for four windows: the most recent hour, the most recent day, the most recent thirty days, and all time.
Breaking rankings out by country or category is a natural follow-up, but it does not change the architecture. Each extra dimension simply becomes part of the key, so a list for India in the music category is just another window keyed differently. Naming this early shows the interviewer you have thought about extension without letting it widen the core scope.
Count every view
Each video view counts toward the rankings.
view events
Query the top K
Return the K most viewed videos, with their view counts.
K ≤ 1,000
Time windows
Last hour, last day, last month, and all time.
1h · 1d · 30d · all
- Out of scope: per-country and per-category lists — same design, more keys
Non-Functional Requirements
Freshness is bounded at about one minute: a video going viral should appear in the hourly list quickly, but nobody needs second-by-second precision. Reads must be fast, with a p99 under 100 ms, because the list sits on high-traffic pages. That requirement alone rules out any counting at query time.
We target an exact top list. A ranking where a video sits at number three when it truly belongs at number nine is visible and embarrassing, though asking whether approximate is acceptable is a sharp clarifying question. Lastly, ingest is enormous, billions of events per day, and dropping them is not allowed, so the pipeline must scale horizontally and survive crashes without losing or double-counting views.
Fresh
Rankings are at most about a minute behind.
≤ 1 min delay
Fast reads
A top-K query returns almost instantly.
p99 < 100 ms
Accurate
The top list must be right, not just roughly right.
exact top K
Huge write volume
Billions of view events a day, without losing any.
horizontal scale
Scale Estimation
Assume 10 billion views per day. Dividing by the seconds in a day gives roughly 116,000 events per second on average, and peaks around 350,000 per second are plausible. Assume about 4 billion videos. A video ID plus a counter is roughly 16 bytes, so holding one counter per video needs about 64 GB, which fits across a modest cluster but not comfortably on a single machine.
Contrast that with the output. Each window's answer is at most 1,000 entries, a few kilobytes. When writes are this heavy and answers this small, the right move is to do the counting continuously as events stream in, and to compute the ranked lists ahead of time so reads become a lookup of a tiny precomputed result.
10billion
Views per day
116K avg
View events per second
≈ 350K/s at peak
4billion
Videos
× 16 B ≈ 64 GB of counters
1000videos
Answer per window
tiny — precompute it
Huge write stream, tiny answer → aggregate in the stream, precompute results
Core Entities & API
The domain needs only three entities: a Video, a View event and a Time window such as 1h or 30d. Treating the window as a first-class concept makes it easy to add new ones later without changing the read path.
Readers call GET /top?window=1h&k=100 and receive an ordered list of video IDs with view counts. Views arrive through an internal POST /views carrying video ID, user ID and timestamp, and it returns 202 because the event is accepted into a stream rather than counted synchronously. In a real deployment the player emits these events directly to the ingestion tier, so this endpoint is more of a contract than a public API.
Core entities
VideoView eventTime window
API
- GET /top?window=1h&k=100→ [ { video_id, views } ]
- POST /views { video_id, user_id, ts }→ 202 accepted
High-Level Design
Players emit a view event per playback into Kafka, using the video ID as the partition key. That choice is load-bearing: every view of a given video lands in the same partition, so exactly one downstream task owns its count. A Flink job consumes the stream and accumulates counts per video per minute in memory, flushing compact batches rather than issuing a write for every view.
Those minute-level counts are persisted to a counts store, which acts as the source of truth for rebuilding any window after a failure. In parallel, a top-K builder keeps one leaderboard per window and periodically (every few seconds) publishes the current lists into a Redis results cache. The read API is deliberately dumb: it fetches a precomputed list from Redis and returns it. Nothing is counted or sorted on the request path.
Deep Dive 1 — Exact vs Approximate
A database row per video, incremented on each view, is exact and easy to explain. But it means over a hundred thousand row updates per second, and a single viral video concentrates a large share of them on one hot row, creating lock contention exactly when traffic peaks.
A Count-Min Sketch uses a small grid of counters indexed by several hash functions. Each event increments one cell per hash row, and a video's estimated count is the smallest value among its cells. Memory is fixed and tiny, but collisions can inflate counts (never deflate them), and since the sketch stores no IDs it must be paired with a heap that tracks current leaders.
The chosen design keeps exact counters inside the stream processor, sharded by video ID. Since each counter lives in exactly one partition, capacity grows by adding partitions. If memory ever becomes the constraint, a hybrid works well: run a sketch as a cheap first-pass filter and keep exact counts only for videos whose estimate is high enough to possibly reach the top list.
Counter row per video
- + Exact and simple
- − 116K row writes / s
- − Hot rows for viral videos
Count-Min Sketch
- + Tiny, fixed memory
- + Very fast
- − May over-count
- − Needs a heap for top K
Sharded stream countsChosen
- + Exact top K
- + Scales by partitions
- − More memory than a sketch
- Sketch: a few hash rows of counters · estimate = minimum across rows
- Memory tight? Sketch as a filter, exact counts only for heavy hitters
Deep Dive 2 — The Stream Pipeline
Partitioning by video ID routes all of one video's views to a single counting task. That task sums events in memory and, at each minute boundary, emits a tuple of video, minute and count, shrinking a firehose of raw events into far fewer records. Each partition also maintains a min-heap of its local top K.
Merging is where partitioning pays off. Because no video's count is split across partitions, the global top K must be contained within the union of the local top-K lists. Combining N small heaps therefore gives an exact global answer without scanning every counter. Viral videos are handled by pre-combining at the ingest tier, which sends one summed record per video per second instead of millions of individual events. For crash safety, Flink snapshots its state together with the Kafka offsets it has consumed, so a restart resumes from a consistent point and no view is applied twice.
- 1Partition by video IDAll views of a video reach one counter task
- 2Pre-aggregateSum in memory → emit (video, minute, count)
- 3Local top KEach partition keeps a heap of its own top K
- 4Merge the listsN small lists → the exact global top K
- 5Viral videosCombine counts early so one partition isn't overloaded
- Checkpoints + Kafka offsets → no view counted twice after a crash
Deep Dive 3 — Time Windows
Every window is assembled from per-minute buckets. For the hourly ranking, each new minute is added and the minute that just dropped off the back is subtracted. Only videos that appear in those two buckets need updating, which keeps the work proportional to activity rather than to the total catalogue.
Long windows would be wasteful at minute granularity: thirty days is over 43,000 minutes. Instead, minutes roll up into hourly buckets and hours into daily ones, so a thirty-day window is maintained from about thirty day buckets. All time is simply a running total that only ever increases, and a nightly batch job checks it against raw events to correct any drift. Finally, the builder publishes the top 1,000 for each window into Redis every few seconds, which is why reads stay well inside the latency target.
Minute buckets as building blocks
Every window is built from per-minute counts per video.
Slide: add the new, subtract the old
Last hour = + newest minute − the minute that just fell out.
Coarser buckets for long windows
Minutes → hours → days; 30 days needs only about 30 day buckets.
All time is a running total
Never subtract; a nightly batch job reconciles it with raw events.
Precompute every window
Publish the top 1,000 per window every few seconds to Redis.
Trade-offs
Exact counting costs memory, while a sketch saves memory at the price of occasional over-counts; the hybrid filter is the escape hatch if the budget tightens. Publishing more often improves freshness but burns compute, and a few seconds is a comfortable middle ground given the one-minute freshness target.
Coarse buckets make long windows cheap, but those windows advance in bigger jumps, so the thirty-day list might shift once a day rather than smoothly. Counting every view is simple, whereas filtering bot traffic adds latency and complexity; for a public ranking, though, trust is worth the delay. The pattern that ties it together: key everything by video, aggregate before storing, and have every window's answer ready before anyone asks.
Exact vs approximate
Exact needs more memory; a sketch is tiny but may over-count.
Freshness vs cost
Publishing every second is fresher, but costs more compute.
Fine vs coarse buckets
Coarse buckets are cheap, but long windows slide in bigger steps.
Count every view vs filter bots
Filtering fake views adds latency — but rankings must be trustworthy.
Partition by video. Pre-aggregate. Precompute every window.
Key takeaways
- Huge write stream, tiny answer: count continuously in the stream and precompute every ranking.
- Partition by video ID so each counter has one owner and local top-K lists merge into an exact global list.
- Count-Min Sketch saves memory but over-counts; use it as a filter if exact counters get too large.
- Build windows from minute buckets, roll up to hours and days, and treat all time as a running total.
- Checkpoint state with Kafka offsets and serve reads straight from Redis to hit sub-100 ms latency.
Interview questions
How do you find the top K most viewed videos in real time?
Stream view events through Kafka partitioned by video ID, count them per minute in a stream processor such as Flink, and keep a local heap of top videos in each partition. Merge the small local lists into a global top K for every window and publish the result to a cache like Redis every few seconds. Reads simply fetch the precomputed list.
What is a Count-Min Sketch and when should you use it for top K?
A Count-Min Sketch is a compact grid of counters addressed by several hash functions. Each event increments one cell in every row, and a lookup returns the smallest of those cells. It uses fixed, small memory but can over-count due to collisions. Use it when memory is tight and slight inaccuracy is acceptable, or as a filter in front of exact counts for likely heavy hitters.
How do you implement a sliding one-hour window for view counts?
Keep counts in per-minute buckets. Each time a new minute closes, add its counts to the hourly totals and subtract the counts from the minute that has just fallen outside the hour. Only videos present in those two buckets change, so the update cost stays small. Longer windows use hourly or daily buckets to avoid tracking tens of thousands of minutes.
Why not use ORDER BY views LIMIT K in a database for top K?
At roughly 116,000 writes per second across billions of rows, a sorted query at read time is far too slow, and constant increments create hot rows for viral videos. The latency target of under 100 ms rules out any heavy work on the request path, so the ranking has to be maintained incrementally in a stream and served from a precomputed cache.
How do you avoid double counting views after a stream processor crash?
Checkpoint the processor's in-memory counters together with the Kafka offsets that produced them. After a failure, the job restores the last snapshot and resumes reading from the matching offsets, so every event is applied exactly once to the state. A nightly batch reconciliation against raw events adds a second safety net for the all-time totals.
Keep practising
- Learn the building blocks in the free system design course.
- Rehearse answers with system design interview questions.
- See which open jobs fit your skills: upload your resume.